Integrating LLMs into pet projects without going broke
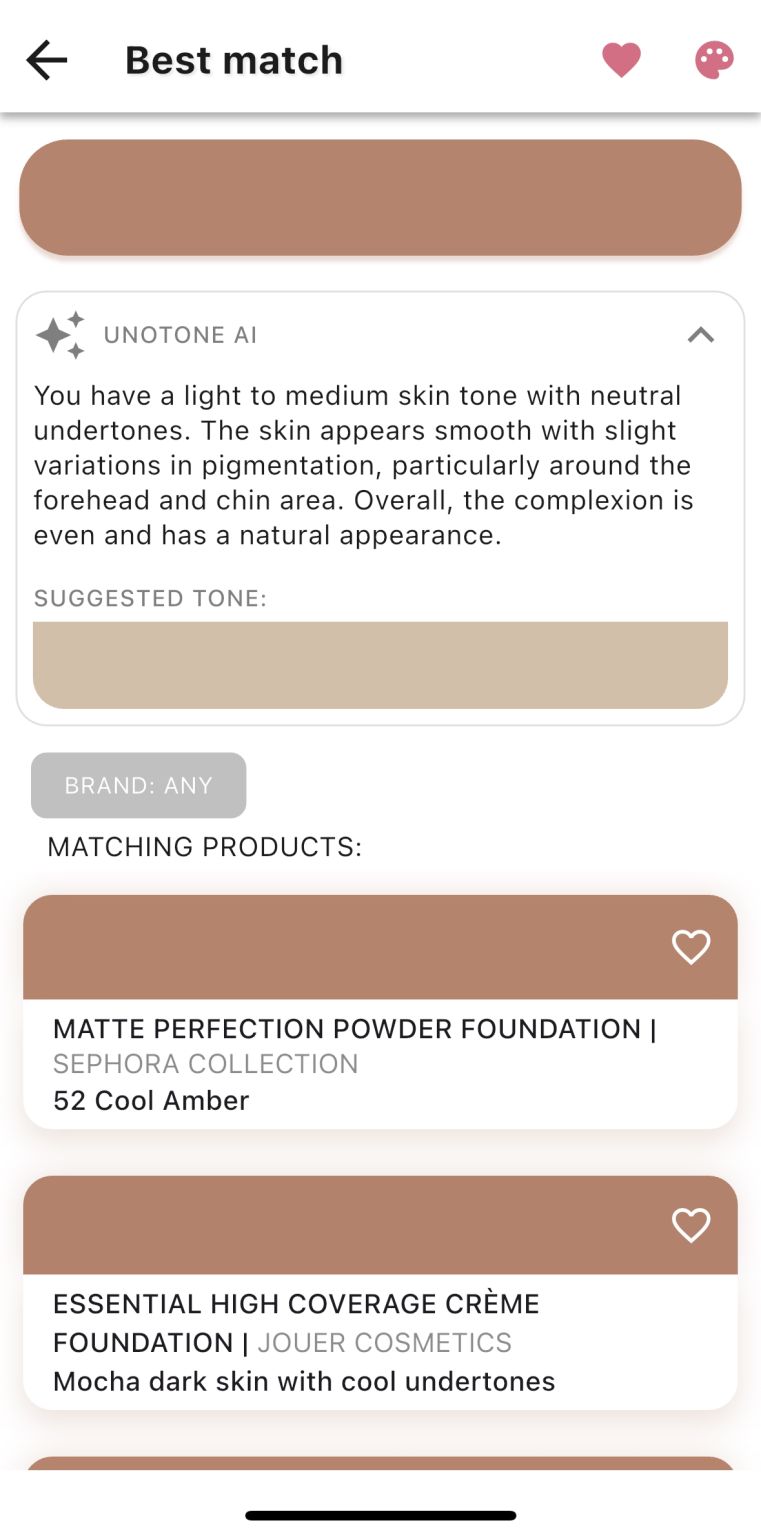
🧑💻 For quite some time, I’ve been exploring ways to integrate LLMs into my projects. While I had some obvious use cases for https://unotone.com 🧠, the cost of deploying them in production was too high 💰. During testing, I could easily spend over $10 within a few hours, especially when working with images.
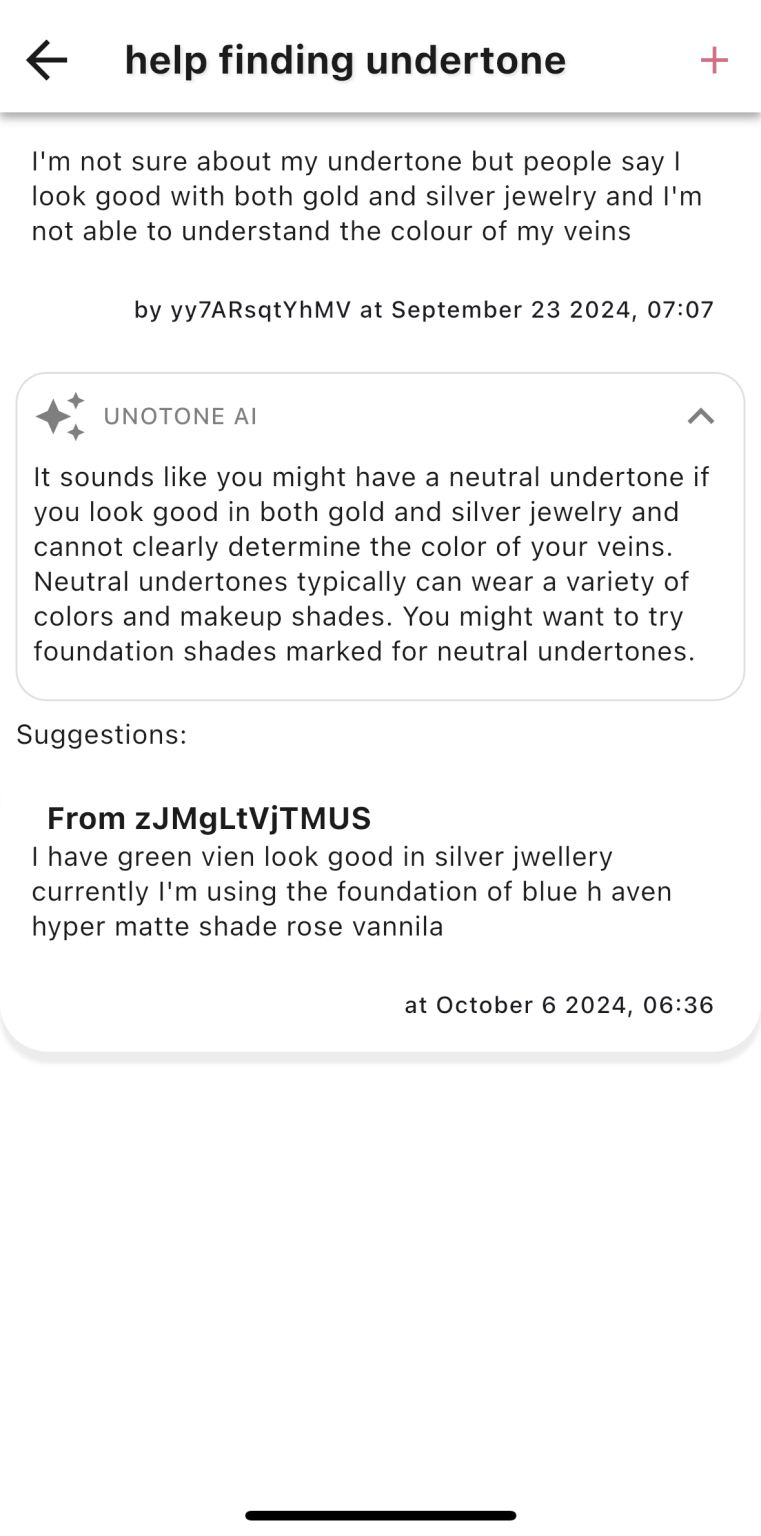
➡️ A few weeks ago, after testing gpt-4-turbo-mini, I decided to roll it out in production 🚀 for skin tone detection and forum discussions. As of today, after processing around 2,000 user submissions 🤳, I see an unbelievable drop in costs, spending just a fraction of what I used to with other models❗️
While I’m not sure if this has affected output quality yet 🧑🔬, the price reduction is a game-changer 💪. I’m hoping to see similar improvements with Claude, which remains quite expensive for file processing.
🫠 One frustrating aspect, though, is the inconsistency in model performance. Reviewing logs, I’ve noticed that the same prompts with the same models sometimes fail—either the response format is off, or I get the “I cannot help you with this task” message. Sometimes the issue resolves on its own, or it requires a few small tweaks to the prompt to fix 🔨. It makes me wonder—should I try deploying an open-source model instead of relying on OpenAI? 🤷♂️ This would be an interesting challenge 🤔
Originally posted on LinkedIn.